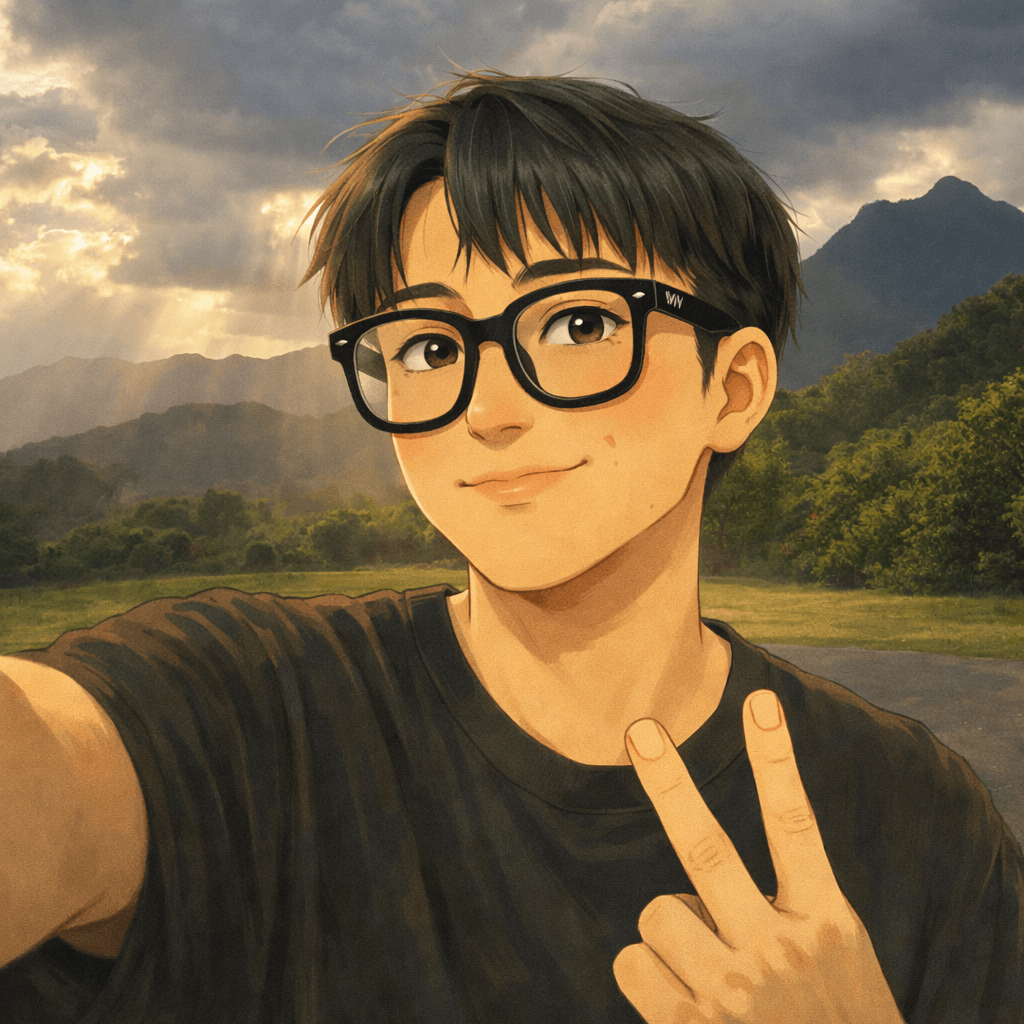
About Me
I am a first-year Ph.D. student at the College of Computing and Data Science, Nanyang Technological University, advised by Prof. Tianwei Zhang. My research interests lie in efficient AI algorithms and systems. Before that, I received my B.Sc. from the Southern University of Science and Technology (SUSTech).
Feel free to reach out if you are interested in discussing research ideas or potential collaborations!
News
- 2026.09 🎉🎉 One first-author paper accepted by NeurIPS 26, see you in Sydney!
- 2026.08 Started my Ph.D. at NTU.
- 2026.04 🎉🎉 One first-author paper accepted by ICML 26, see you in Seoul!
- 2025.08 I began my full-time RA at NTU.
Education
Nanyang Technological University
2026.08 - Present
Full-time Ph.D. at CCDS
2026.08 - Present
Full-time Ph.D. at CCDS
SUSTech
2021.09 - 2025.06
Major in Data Science and Big Data Technology
2021.09 - 2025.06
Major in Data Science and Big Data Technology
Other Experience
Nanyang Technological University
2025.08 - 2026.08
Research Assistant at Aumovio-NTU Corporate Lab
2025.08 - 2026.08
Research Assistant at Aumovio-NTU Corporate Lab
SIGS, Tsinghua University
2024.08 - 2025.02
Research Intern at MMLab@SIGS
2024.08 - 2025.02
Research Intern at MMLab@SIGS
Publications
(* equal contribution · † corresponding author · ‡ project leader)
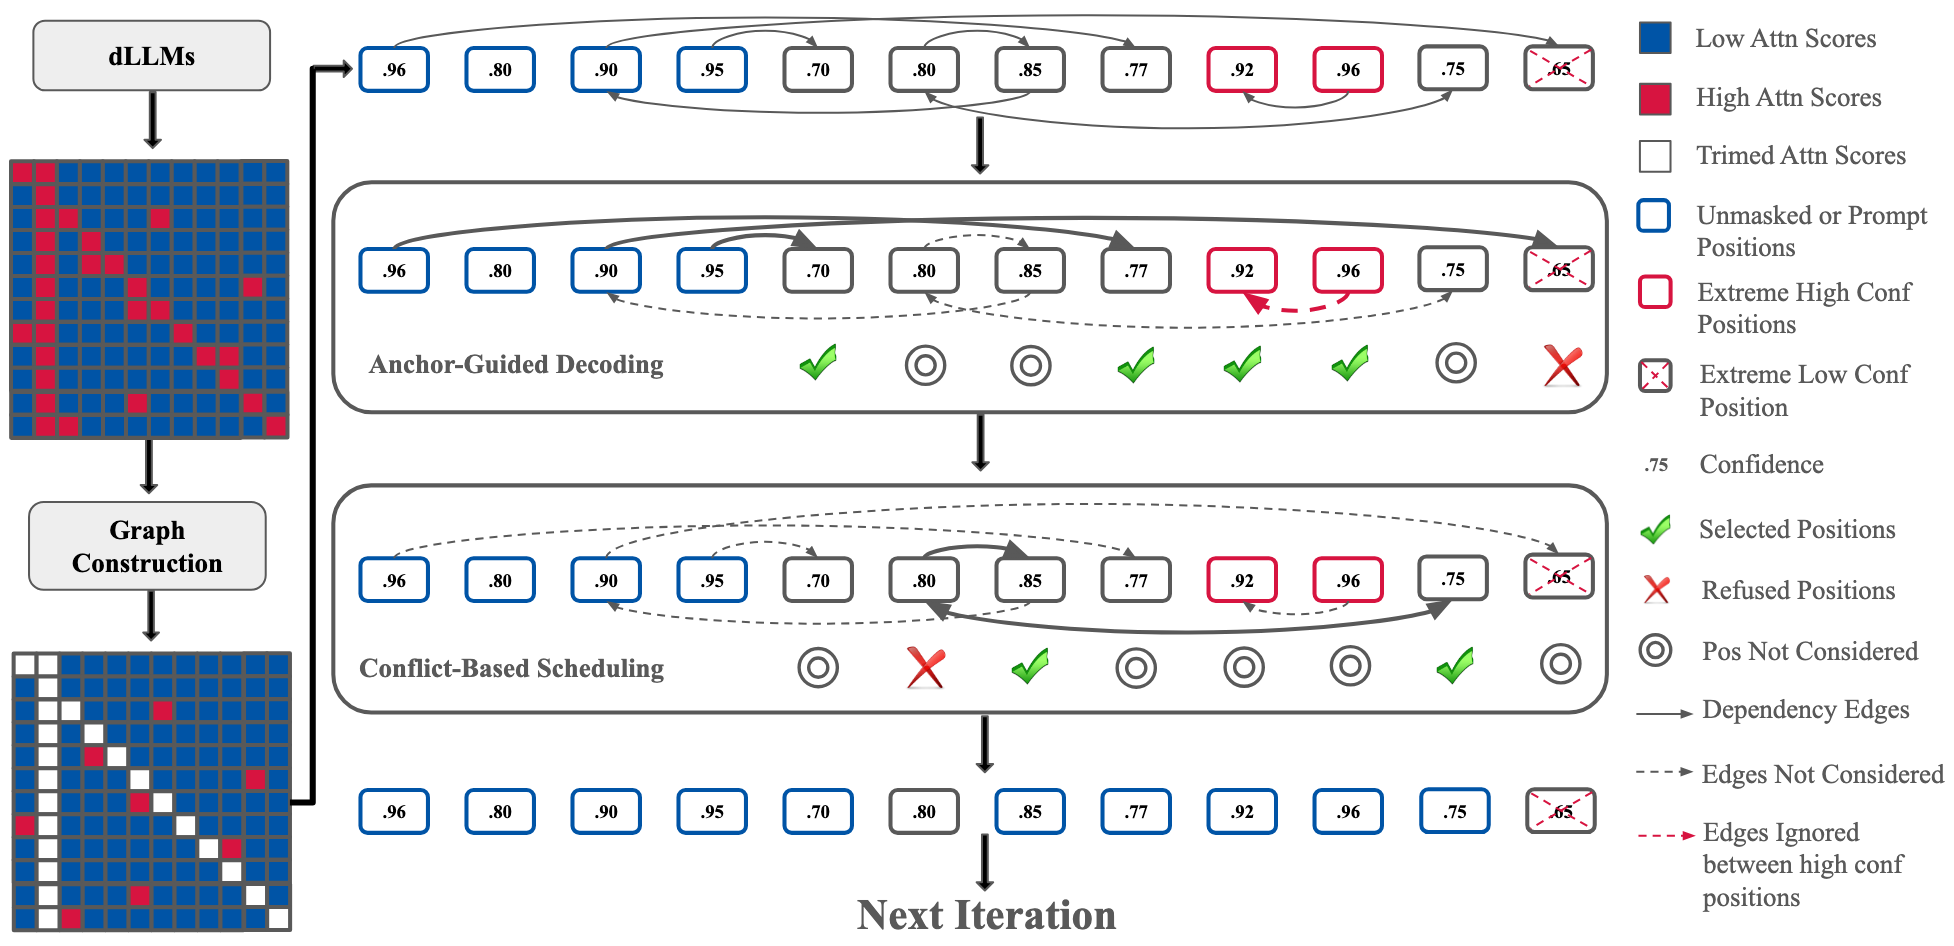
DAWN: Dependency-Aware Fast Inference for Diffusion LLMs
Lizhuo Luo, Zhuoran Shi, Jiajun Luo, Zhi Wang, Shen Ren, Wenya Wang, Tianwei Zhang†.
DAWN, a training-free, dependency-aware method for fast inference of diffusion LLMs. DAWN speedups the inference by 1.80 - 8.06× over baselines while preserving the generation quality.
NeurIPS 2026 [arXiv] [code]
Lizhuo Luo, Zhuoran Shi, Jiajun Luo, Zhi Wang, Shen Ren, Wenya Wang, Tianwei Zhang†.
DAWN, a training-free, dependency-aware method for fast inference of diffusion LLMs. DAWN speedups the inference by 1.80 - 8.06× over baselines while preserving the generation quality.
NeurIPS 2026 [arXiv] [code]
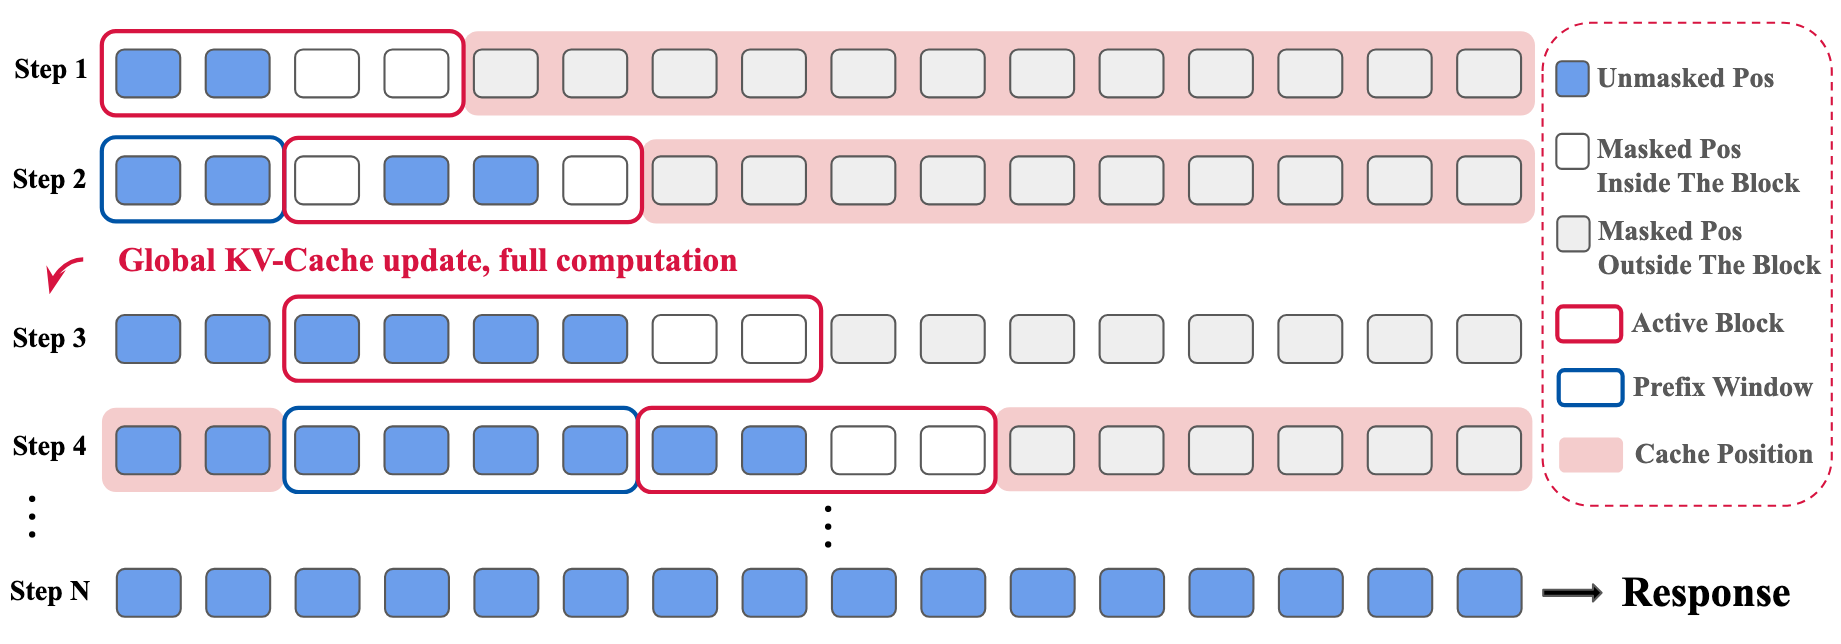
DSB: Dynamic Sliding Block Scheduling for Diffusion LLMs
Lizhuo Luo*, Shenggui Li*, Yonggang Wen, Tianwei Zhang†.
Dynamic Sliding Block (DSB), a training-free block scheduling method that uses a sliding block with a dynamic size to overcome the rigidity of the naive block; DSB Cache, a training-free KV-cache mechanism tailored to DSB, improves both generation quality and inference efficiency for dLLMs.
ICML 2026 [arXiv] [code]
Lizhuo Luo*, Shenggui Li*, Yonggang Wen, Tianwei Zhang†.
Dynamic Sliding Block (DSB), a training-free block scheduling method that uses a sliding block with a dynamic size to overcome the rigidity of the naive block; DSB Cache, a training-free KV-cache mechanism tailored to DSB, improves both generation quality and inference efficiency for dLLMs.
ICML 2026 [arXiv] [code]
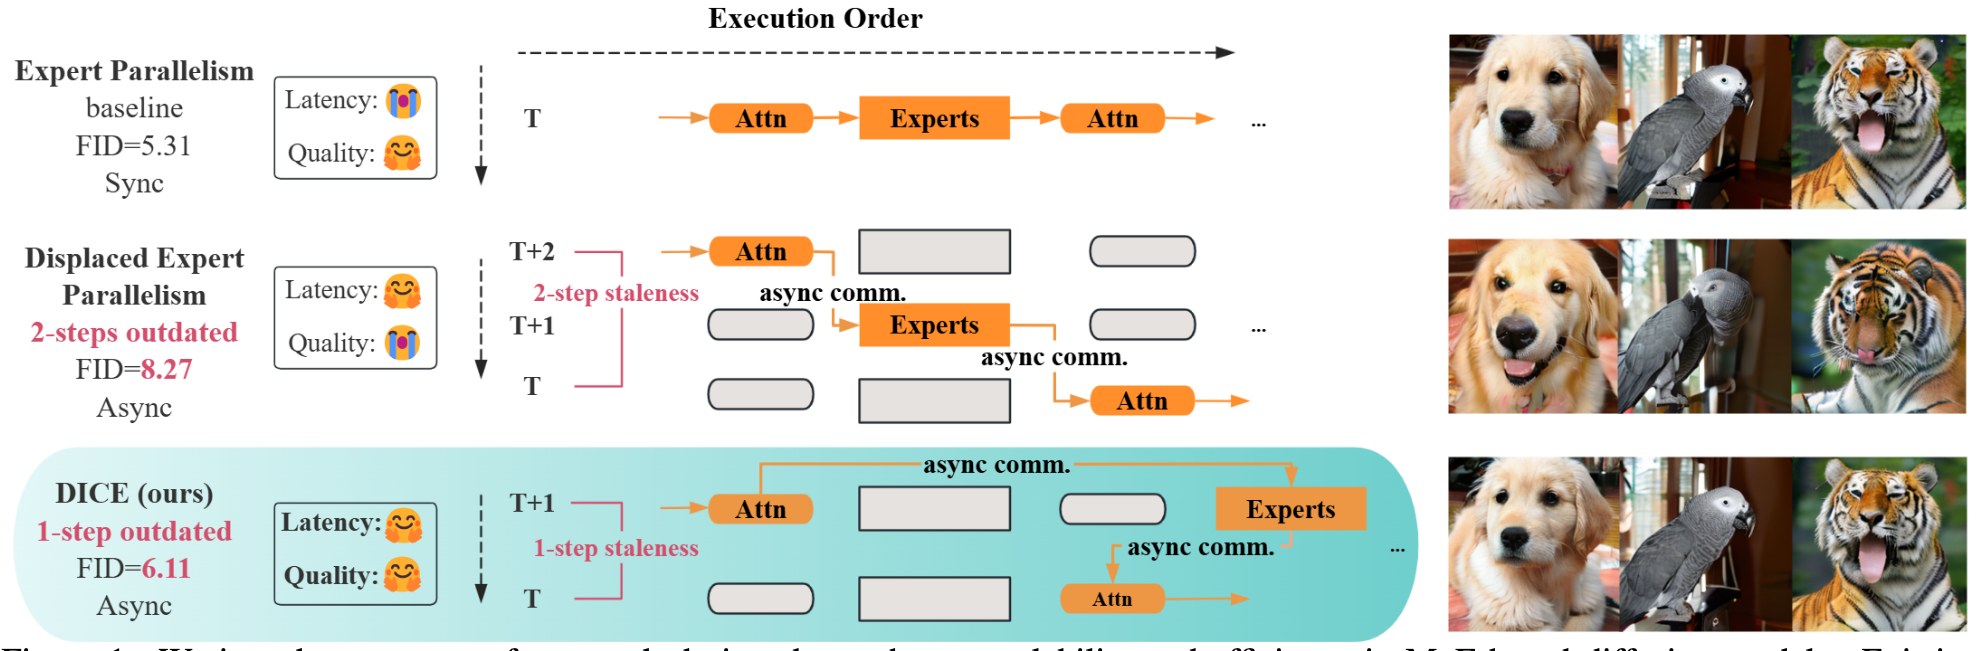
DICE: Staleness-Centric Optimizations for Parallel Diffusion MoE Inference
Jiajun Luo*, Lizhuo Luo*, Jianru Xu*, Jiajun Song, Rongwei Lu, Chen Tang, Zhi Wang†.
DICE, an asynchronous expert-parallel framework for MoE-based diffusion models that overlaps communication and computation to realize faster, more scalable multi-GPU inference, achieving up to 1.26× speedup with minimal quality impact.
ICCV 2025 [arXiv] [code]
Jiajun Luo*, Lizhuo Luo*, Jianru Xu*, Jiajun Song, Rongwei Lu, Chen Tang, Zhi Wang†.
DICE, an asynchronous expert-parallel framework for MoE-based diffusion models that overlaps communication and computation to realize faster, more scalable multi-GPU inference, achieving up to 1.26× speedup with minimal quality impact.
ICCV 2025 [arXiv] [code]
- NeurIPS 2026 DAWN: Dependency-Aware Fast Inference for Diffusion LLMs
[arXiv][code] - ICML 2026 DSB: Dynamic Sliding Block Scheduling for Diffusion LLMs
[arXiv][code] - Arxiv 2025 FlowSpec: Continuous Pipelined Speculative Decoding for Efficient Distributed LLM Inference
[arXiv][code] - ICCV 2025 DICE: Staleness-Centric Optimizations for Parallel Diffusion MoE Inference
[arXiv][code]
Awards
- 2025, Outstanding Graduation Thesis.